
Developers are gaining a significant amount of flexibility in how they build software as GitHub Copilot begins integrating local AI models directly into the Windows ecosystem. By blending high powered cloud scale models with on device intelligence, Microsoft is aiming to give programmers better control over speed, cost, and privacy. Starting later this month, GitHub Copilot will feature an automatic orchestration system that decides in real time whether a specific task should be handled locally on the user’s machine or routed to the cloud.
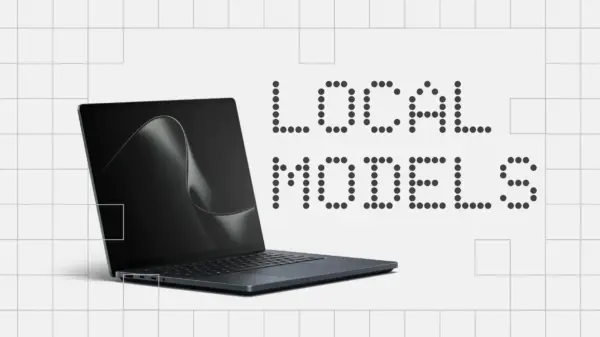
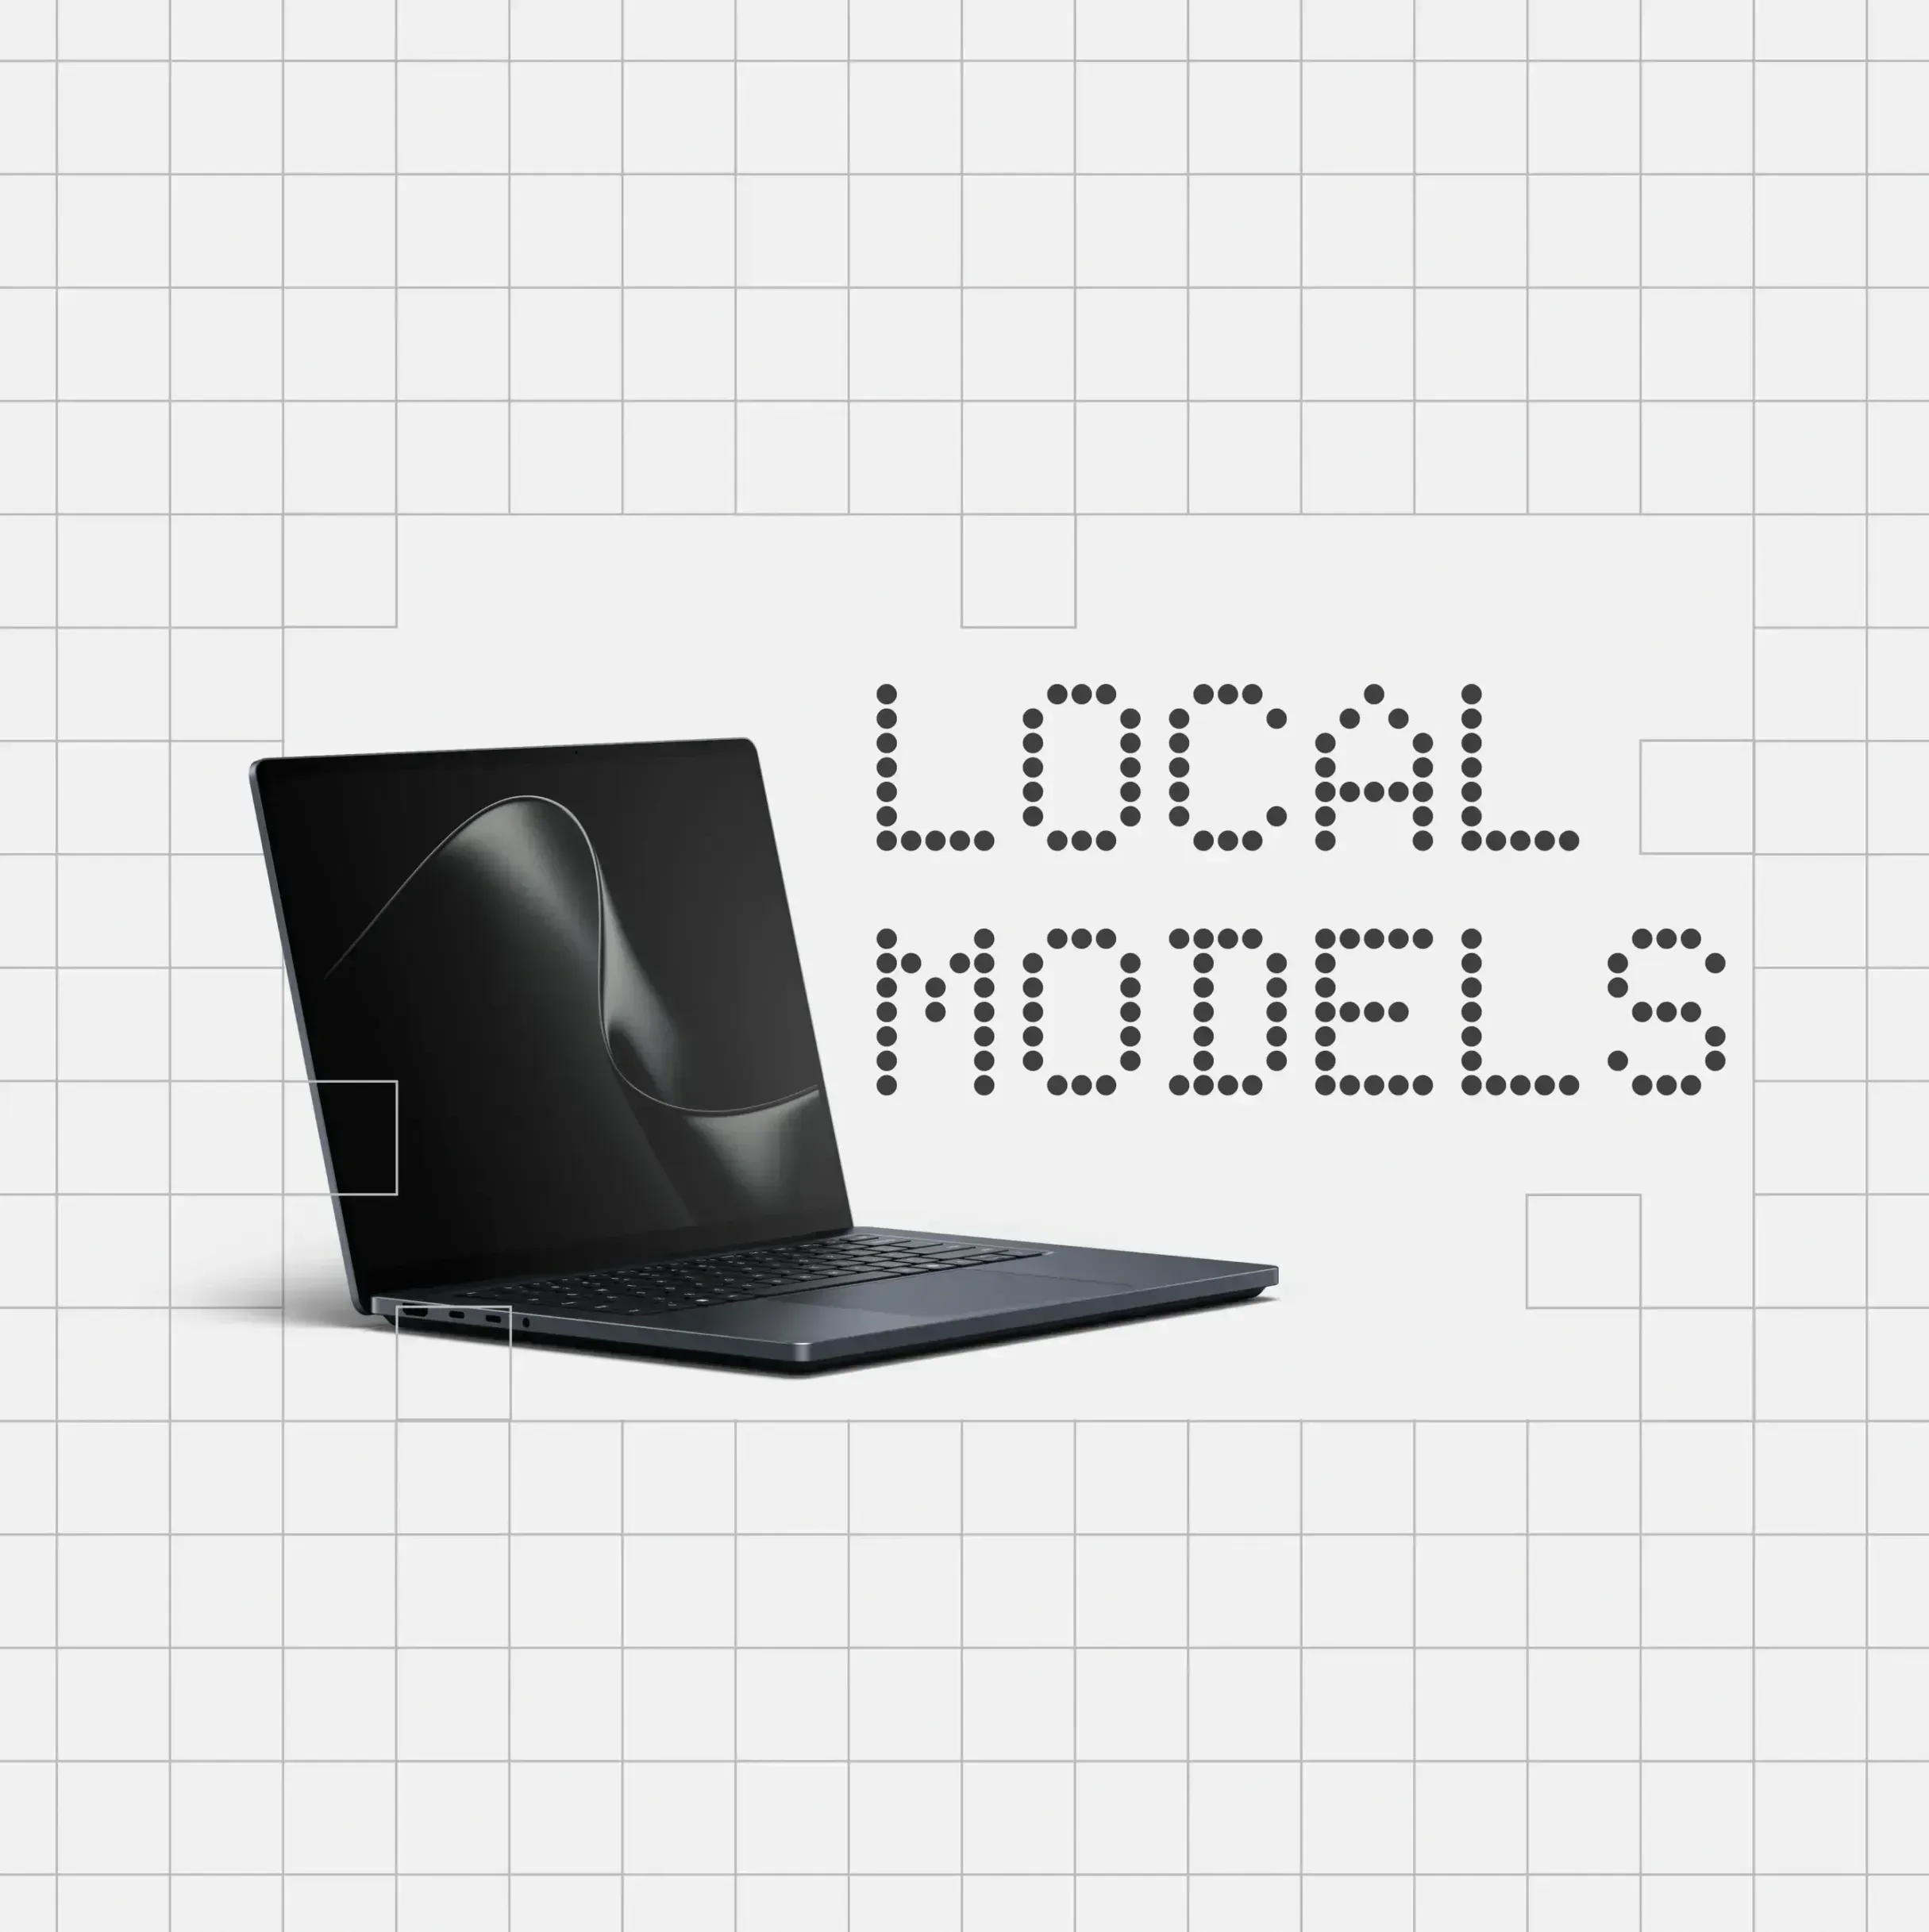
This hybrid approach relies heavily on specialized hardware and secure environments. To keep these autonomous agents safe, Windows has introduced Microsoft Execution Containers, which provide sandboxed spaces where AI can run commands and access files without risking the stability or security of the broader system. For those using high end machines like the Surface Laptop Ultra equipped with NVIDIA RTX Spark GPUs, this means complex coding tasks can now happen at the edge, reducing reliance on external servers and speeding up response times through massive unified memory pools.
At the heart of this local push is a new optimized model called MAI Code 1.1 Flash. Developed by Microsoft AI, this mixture of experts model uses clever techniques like quantization and speculative decoding to shrink its footprint without sacrificing accuracy. Essentially, the team found a way to reduce the model size by eighty percent while maintaining a level of performance that rivals much larger cloud variants. This allows a sophisticated coding assistant to live permanently on a laptop’s drive rather than existing solely in a remote data center.
Users will have two distinct ways to interact with these local capabilities within VS Code and the Copilot app. Those who prefer convenience can use an auto mode where Copilot manages the routing between local and cloud resources behind the scenes based on the complexity of the request. Meanwhile, power users who require absolute control over their environment can manually select local models for specific workflows. While this brings processing closer to home, it does not mean developers are going offline; instead, it creates a fluid movement of data that optimizes every keystroke for efficiency.